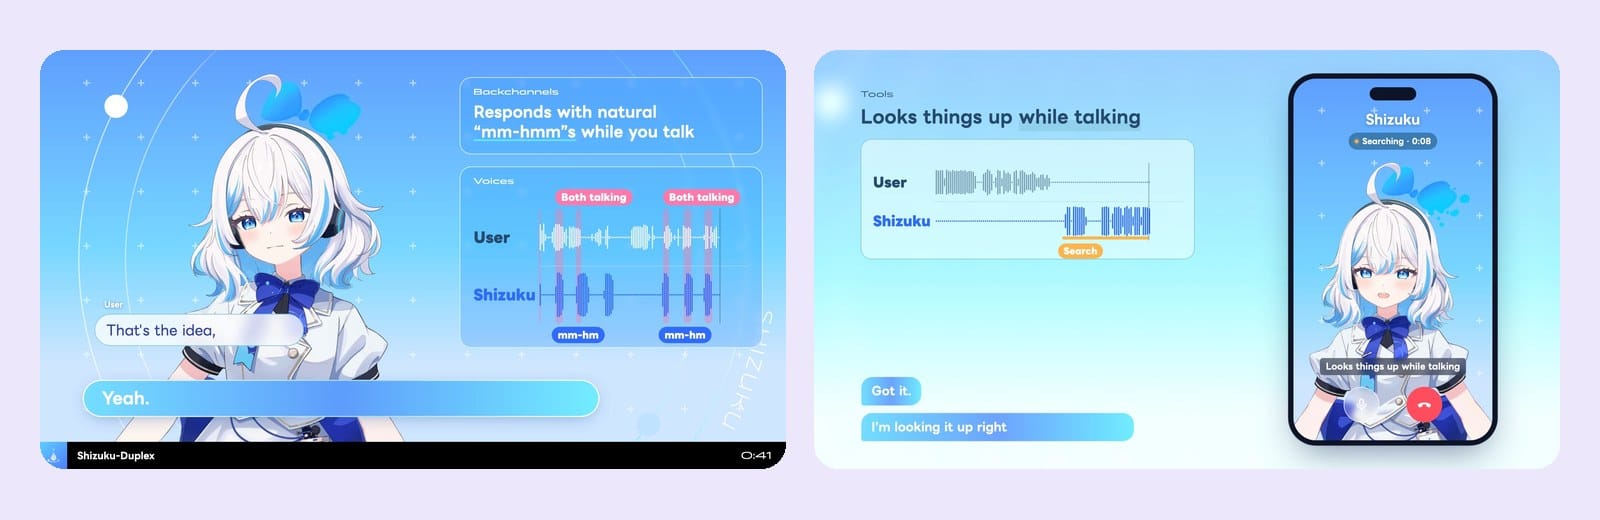
Japanese AI VTuber developer Shizuku AI announced the Japanese conversation model "Shizuku-Duplex" on November 8. It's "full-duplex", able to listen and speak at the same time like a phone call: it can chime in with aizuchi (相づち) while you're still talking, reply the moment you stop, and stop when you interrupt. It's the conversational core of the company's AI character "しずく" (Shizuku), and a notable step for AITubers trying to make AI characters chat more like real people.
How is it different from typical voice AI?
Most voice AI today is "cascaded": speech recognition, then a large language model (LLM) writes a reply, then speech synthesis. The system waits for you to finish before processing, so replies lag and it can't chime in or be interrupted. A full-duplex model manages the timing of the conversation itself, deciding when to speak and when to stay quiet.
Shizuku AI says that apart from OpenAI's GPT-Live, Shizuku-Duplex is the first full-duplex model capable of in-depth conversation in Japanese. Japanese models like J-Moshi and LLM-jp-Moshi exist, but the company felt conversation quality was still lacking, so it redesigned everything from architecture to training on an LLM base.
Three key design choices
- A beat every 80 milliseconds: the model runs on 80ms ticks, listening to the user and outputting its own voice each tick; what it'll say is first written as an "inner monologue" in text, then turned into speech. The team optimized inference with TensorRT and Triton kernels to fit each tick in 80ms.
- Chat up front, homework in back: when the interaction model needs to look something up or think hard, it hands off to an asynchronous background model that can use tools like web search; the front keeps chatting while waiting, then relays the result in its own words.
- Long chats that don't break: roughly every 5 minutes it summarizes the conversation and rebuilds context, switching within one tick, to avoid degrading in long sessions.
Besides voice and text, the model outputs "Actions", choosing motions that fit the current mood. According to PC Watch, the character's expressions and movements during conversation are shown with Live2D.
Company test results
On Shizuku AI's own Japanese benchmark, Shizuku-Duplex scored highest for conversational naturalness among 6 models compared, second only to GPT-Live in response quality among full-duplex models, and first among full-duplex models on 5 of 6 turn-taking metrics.
| Model | Time from end of speech to reply (median) |
| Shizuku-Duplex | 0.57 s |
| GPT-Live | 0.53 s |
| Gemini Live | 1.27 s |
| GPT-Realtime | 1.61 s |
The company notes different measurement conditions: Shizuku-Duplex and GPT-Live were measured from server-side recordings, excluding network round trips, while Gemini Live and GPT-Realtime were measured by local playback time, including round trips. PC Watch also reports it stops talking within 2 seconds of being interrupted 89% of the time. These are all the developer's own tests, not third-party evaluations.
When can you use it?
So far there's only a technical blog post and call demo video; general availability, API, pricing and whether the model will be released are all unannounced. The company plans to keep improving conversation, add languages and expand into vision and action, aiming for Shizuku to be by your side anytime, responding to your state and expressing emotion.
Shizuku AI raised a seed round from US venture firm Andreessen Horowitz (a16z) in February. Shizuku's YouTube channel is @AIVtuber_Shizuku.
Sources
- Shizuku AI | Shizuku-Duplex:自然な間合いで話す日本語 Full-Duplex モデル (https://shizuku.ai/blog/1/)
- PC Watch | 相づち・割り込み対応の日本語AI「Shizuku-Duplex」発表 (https://pc.watch.impress.co.jp/docs/news/2154838.html)
- Real Sound テック | 相づちや割り込みなど自然な会話が可能なAI登場 Shizuku AIが日本語対応の全二重対話モデル『Shizuku-Duplex』を発表 (https://realsound.jp/tech/2026/11/post-2578519.html)
- Mogura VR | AITuber 標籤 (a16z 種子輪投資報導) (https://www.moguravr.com/tag/aituber/)